Agentic systems
Multi-step agents that verify, retry, and finish work over hours — not one-shot chat replies.
We don't pitch AI. We ship it. Live products, public evals, one lab behind it all.
What we do
Multi-step agents that verify, retry, and finish work over hours — not one-shot chat replies.
From lab experiment to production product — with evals, observability, and real user load.
Multimodal scoring for children's video — transcript, frames and context. Measured in public by SafeWatch-Bench, it decides what enters a learning plan.
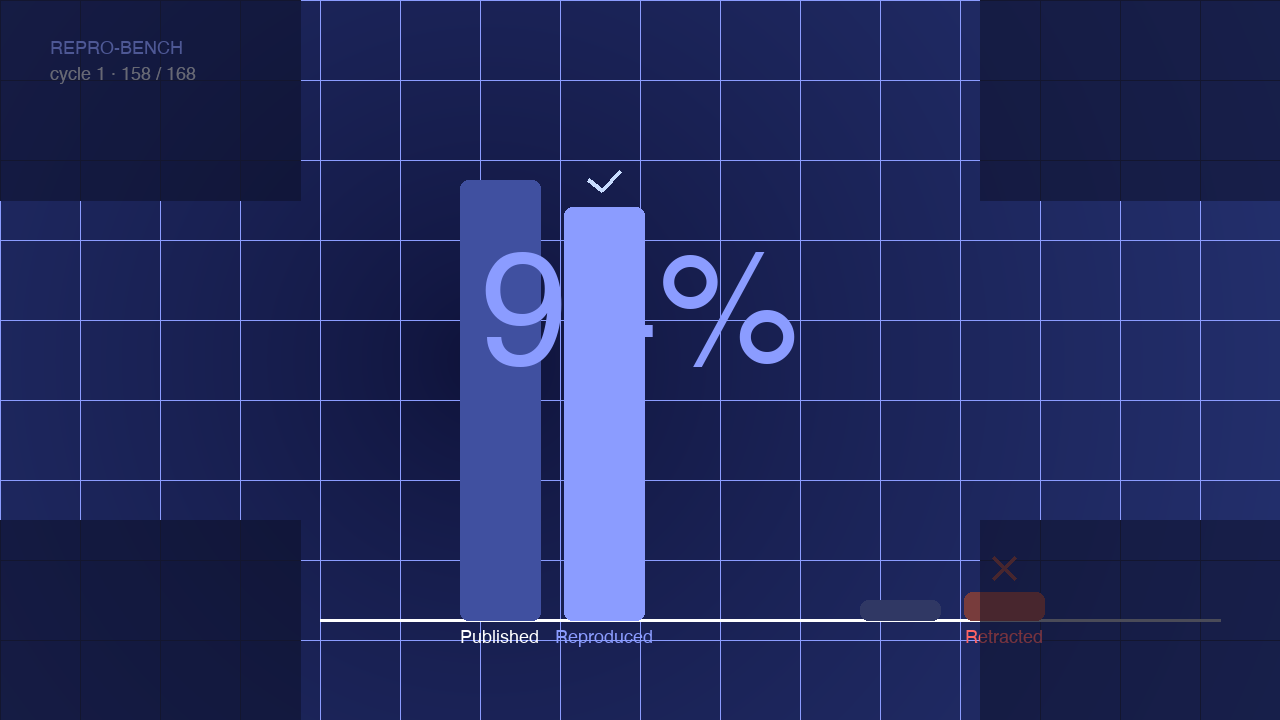
Public benchmarks for agent reliability over days and weeks — the bar before anything ships.
One real workflow of a business automated per engagement — replies, bookings, reporting — shown running before any proposal.
SAF-T, ATCUD, and GDPR signal detection engineered for fiscal quarters, not checkbox audits.
Lab evals
Public benchmarks tied to real products — not slide decks.
About
We don't sell AI promises. We show what's already working.
Every idea enters lab mode before it becomes a product. Our shipping record is the portfolio — when we advise a business, we do it with the credibility of people who already run systems in production.
Join the Lab
Researchers, engineers, founders — if you want to ship at the edge of possible, say hello.
hello@lemu-lab.com